PhysWorld: From Real Videos to World Models of Deformable Objects via Physics-Aware Demonstration Synthesis

1 Harbin Institute of Technology, Harbin, China
2 Huawei Noah's Ark Lab
Research Teaser Image

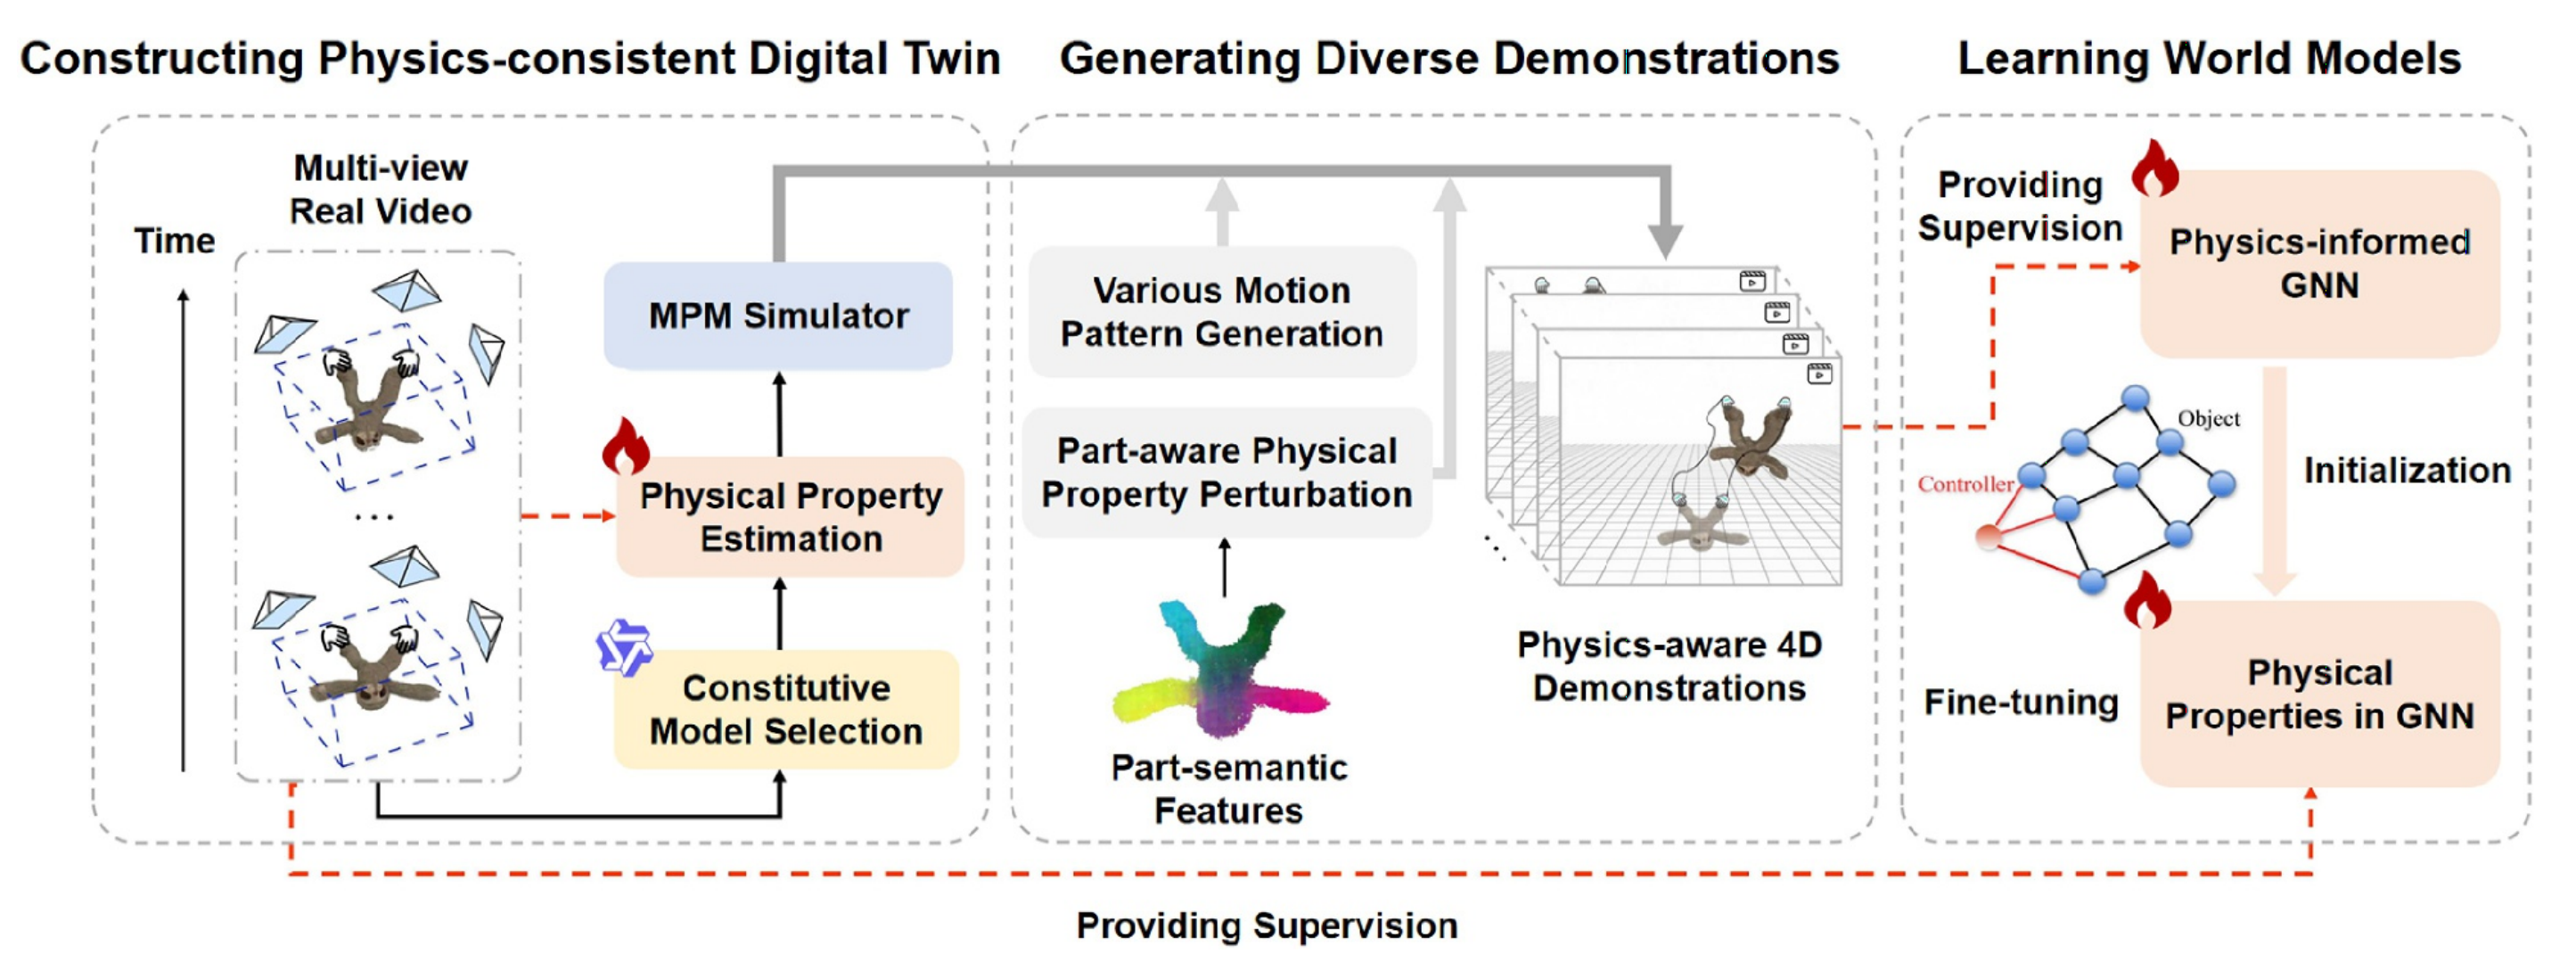
Overview of PhysWorld. The framework first constructs a physics‐consistent digital twin from videos, then uses it to generate diverse 4D demonstrations, and finally trains a GNN‐based world model for real‐time future state prediction.

Abstract

Interactive world models that simulate object dynamics are crucial for robotics, VR, and AR. However, it remains a significant challenge to learn physics‐consistent dynamics models from limited real‐world video data, especially for deformable objects with spatially varying physical properties. To overcome the challenge of data scarcity, we propose PhysWorld, a novel framework that leverages a simulator to synthesize diverse and physically plausible demonstrations for training efficient world models. Specifically, we first construct a physics‐consistent digital twin within an MPM simulator via constitutive model selection and global‐to‐local optimization of physical properties. Subsequently, we apply part‐aware perturbations to the physical properties and generate various motion patterns for the digital twin, synthesizing extensive and diverse demonstrations. Finally, using these demonstrations, we train a lightweight GNN‐based world model that is embedded with physical properties. The real‐world data is further used to refine the physical properties. PhysWorld achieves accurate and fast future predictions for various deformable objects, and also generalizes well to novel interactions. Experiments show that PhysWorld has competitive performance while enabling inference speeds 47 times faster than the recent state‐of‐the‐art method, that is, PhysTwin.

Action-Conditioned Future Prediction

With Point Trajectories
Without Point Trajectories

Figure A: Visual results of action-conditioned future prediction. Drag the slider to compare predictions with and without visualization of point trajectories predicted by GNNs. (The consistent coloring of points and trajectories is intended solely for enhanced visualization and carries no underlying significance. The lower-opacity segments represent the ground truth motion of the object.)

Figure B: Visual results of action-conditioned future prediction compared with PhysTwin. Our method’s predicted positions show closer alignment with ground truth compared to PhysTwin.

-->

Unseen Interaction

Figure C: Generalization to unseen interactions. As representative examples, we consider two unseen interaction scenarios: lifting a pushed rope and rotating a lifted sloth. The results show that PhysWorld generates physically plausible predictions, while PhysTwin suffers from artifacts such as fracture-like rope distortions and unnatural foot folding.


Figure D: Qualitative comparison with PhysTwin on unseen interactions with a rope and a cloth recorded by a real robot (shaded regions indicate the ground truths).

Model-Based Planning on a Physical Robot

Figure G: Qualitative results of Real-robot model-based planning. With PhysWorld GNN models and MPPI control method, the rope, the toy sloth and the cloth are transferred from the initial configurations to the target ones (shaded regions indicate the target configurations).

BibTeX

@misc{yang2025physworldrealvideosworld,
      title={PhysWorld: From Real Videos to World Models of Deformable Objects via Physics-Aware Demonstration Synthesis}, 
      author={Yu Yang and Zhilu Zhang and Xiang Zhang and Yihan Zeng and Hui Li and Wangmeng Zuo},
      year={2025},
      eprint={2510.21447},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2510.21447}, 
}